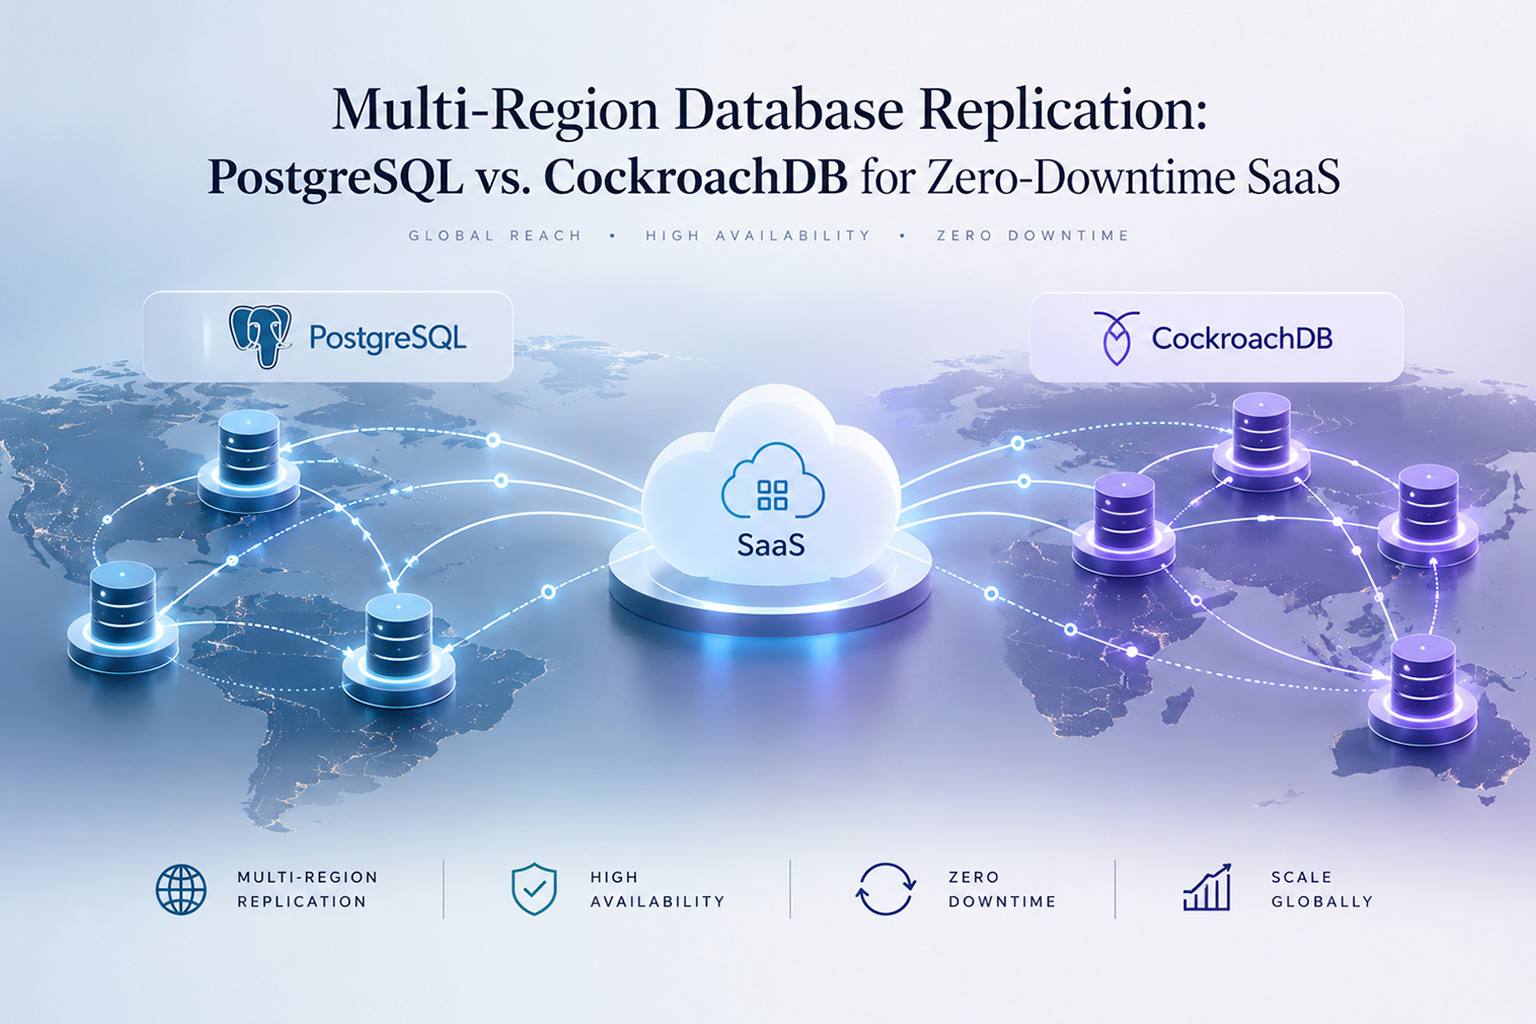
Multi-Region Database Replication: PostgreSQL vs. CockroachDB for Zero-Downtime SaaS
07 Oct 2026
Quick Summary: Which Database Is Better for Multi-Region Zero-Downtime SaaS?
Neither is universally better. PostgreSQL can support sophisticated multi-region architectures, but multi-writer designs need extra replication tooling and careful conflict management. CockroachDB is built as distributed SQL with native multi-region operation. The right choice depends on write distribution, consistency needs, data residency, and existing PostgreSQL expertise.
For teams weighing PostgreSQL vs. CockroachDB for multi-region SaaS in 2026, the decision is architectural rather than a feature checklist. This guide covers where each approach fits and how to plan enterprise multi region database architecture around availability goals.
The Global Scale Bottleneck: Why Single-Region Databases Become a Problem
Most SaaS platforms start in one region. Pressure builds when users sit far from the database, availability targets exceed what one region can deliver, and customers ask where their data lives.
Distance is the first constraint. Light in optical fiber travels at roughly two-thirds of its vacuum speed, so geography sets a hard lower bound on round-trip time. Actual latency is higher and depends on routing, peering, and cloud network conditions, so measure your own paths instead of assuming a figure. What matters architecturally is round-trip count: a request that makes five sequential database calls across an ocean pays that penalty five times.
This is why deploying application servers in several regions does not create a multi-region database. If every instance still writes to one primary, you have moved the latency problem, not solved it. Local read replicas help, but they inherit replication lag. Add regional failure, recovery objectives, and residency requirements, and the data layer becomes the hard part of going global.
PostgreSQL Multi-Region vs. CockroachDB
PostgreSQL is a mature relational database whose multi-region capability is assembled from components. Streaming replication supports primary/standby deployments, logical replication publishes table-level changes to other clusters, and tools such as Patroni coordinate failover. Read replicas, application-level routing, and extensions such as Spock, which provides asynchronous multi-master replication, extend the model further. Many production systems run this way successfully. The trade-off is ownership: replication topology, failover, conflict handling, and routing live partly in tooling and partly in your application, and complexity grows as you move from one writer to several.
CockroachDB is a distributed SQL database. Data is divided into ranges, each replicated across nodes, with Raft consensus keeping a range's replicas consistent. Transactions are serializable by default and can span ranges and regions. Locality settings control where data lives, and table localities such as REGIONAL BY ROW can home individual rows in specific regions. The platform manages replica placement and coordination, but physics still applies: a write needs acknowledgment from a quorum of replicas, so quorum placement shapes latency.
|
Architectural Factor |
Multi-Region PostgreSQL |
CockroachDB |
|
Core model |
PostgreSQL relational database extended with replication/HA/distribution tooling |
Distributed SQL database |
|
Multi-region writes |
Possible with specific architectures/extensions; complexity depends on design |
Designed for distributed multi-region operation |
|
Replication |
Streaming/logical replication and other approaches |
Distributed replication with consensus |
|
Data locality |
Requires architectural design and tooling |
Built-in locality/partitioning capabilities |
|
Operational complexity |
Can increase substantially with multi-writer/distributed designs |
Distributed architecture shifts complexity into the platform |
|
Existing PostgreSQL ecosystem |
Major advantage |
Migration may require architectural/application changes |
|
Best fit |
Teams with strong PostgreSQL expertise and specific architecture requirements |
Applications designed around distributed SQL and multi-region workloads |
The Four Technical Pillars of Multi-Region Database Availability
1. Distributed Transactions and Consensus
Asynchronous replication, the common PostgreSQL pattern, commits locally and ships changes afterward. Commits stay fast, but a failover can lose recent transactions and replicas can serve stale reads. PostgreSQL also supports synchronous replication, which waits for standby confirmation and adds that round trip to each commit. CockroachDB replicates synchronously through Raft: a write commits once a majority of a range's replicas acknowledge it. That preserves strong consistency, but if the majority spans regions, writes pay cross-region latency. Consensus coordinates state under defined failure models. It does not eliminate application bugs, misconfiguration, or every partition scenario.
2. Data Locality and Geo-Partitioning
Locality keeps data near the users or workloads that need it. In CockroachDB, regional-by-row tables suit tenant-aware designs where a customer's data is mostly accessed from one geography. In PostgreSQL, similar outcomes come from regional clusters, partitioning, or per-region databases behind a routing layer. Locality can reduce latency, isolate regional workloads, and support residency controls.
It does not settle legal questions. GDPR does not blanket-prohibit storing EU personal data elsewhere; it sets conditions for transfers outside the EEA, such as adequacy decisions or standard contractual clauses. Contracts, sector rules, and customer commitments may be stricter. Have legal and compliance professionals define the requirements, then validate placement, backups, and replicas against them.
3. Multi-Writer Architectures and Conflict Management
Multi-region reads are straightforward to scale. Multi-region writes are not, because concurrent updates to the same data must be reconciled. In PostgreSQL, native logical replication does not replicate DDL or sequence state, and multi-master tools such as Spock rely on conflict handling like last-update-wins or delta-apply columns. You also need non-colliding identifiers, application routing, and tested failover behavior.
Not every PostgreSQL deployment needs this. A single-writer primary with regional read replicas avoids write conflicts entirely, and CRDTs are one conflict-resolution technique among several, not a requirement. CockroachDB takes a different route: each range has a leaseholder coordinating its writes, and serializable transactions replace after-the-fact conflict resolution. The cost appears as coordination latency, and contention on hot rows can still trigger transaction retries.
4. Zero-Downtime Schema Changes and Migrations
Schema changes grow riskier as regions multiply, because application versions and database schemas rarely update at the same instant. Use expand-and-contract: add new structures, deploy code that writes to both, backfill, switch reads, then remove the old structure. Avoid long-held locks; in PostgreSQL, that means tools such as CREATE INDEX CONCURRENTLY and staged constraints. PostgreSQL's logical replication documentation advises applying additive changes to subscribers first.
CockroachDB is designed to run schema changes online, though large backfills still consume resources. Migration tools such as Liquibase or Flyway version and apply changes; they do not make a risky change safe. Rehearse migrations on production-like data and write the rollback plan before deploying.
How to Achieve Near-Zero-Downtime Database Replication Across Regions
Zero downtime is an architectural goal, not a guarantee. No database survives every network partition, schema mistake, or operator error. Use this framework to design for zero-downtime or near-zero-downtime availability:
- Define RPO and RTO for each service tier.
- Decide whether you need multi-region reads, writes, or both.
- Choose synchronous or asynchronous replication based on consistency needs and tolerable latency.
- Design regional failover before deploying replication: who promotes, how traffic moves, how a failed region rejoins.
- Define data locality and residency requirements with legal input.
- Make writes idempotent where appropriate so retries after failover do not duplicate work.
- Test failover and recovery regularly, including partition scenarios.
- Ship backward-compatible schema migrations.
- Monitor replication lag or consensus health alongside application latency.
- Document operational runbooks.
PostgreSQL vs. CockroachDB — Which Should a SaaS Company Choose?
PostgreSQL may be the better fit when:
• Your team has deep PostgreSQL expertise and the application relies on PostgreSQL-specific capabilities.
• Most workloads are regional rather than globally write-distributed.
• Read replicas and carefully designed failover meet your availability targets.
• You want maximum ecosystem compatibility and the complexity of distributed SQL is not justified.
CockroachDB may be worth evaluating when:
• Multi-region operation is a core requirement, with geographically distributed writes.
• Strong consistency across regions and data locality are major concerns.
• You are willing to adopt a distributed SQL platform and can accommodate its SQL and feature-compatibility differences.
Neither is automatically cheaper, faster, or easier. Compare total cost of ownership, including migration effort, operational skills, and licensing, using your own workload in a proof of concept.
Frequently Asked Questions
Can PostgreSQL run in an active-active multi-region configuration?
Yes, with additional technologies such as multi-master extensions. Write conflicts, consistency, failover, and operational complexity must be addressed deliberately.
How does CockroachDB handle cross-region read/write latency?
Through locality settings, leaseholder and range placement, replication, and consensus. Data homed near its users avoids cross-region hops, but writes still need a quorum, so latency depends on where replicas sit. No fixed figure applies.
Is CockroachDB better than PostgreSQL for multi-region SaaS?
Not universally. PostgreSQL fits regional workloads and teams invested in its ecosystem; CockroachDB fits applications built around distributed writes and native multi-region operation.
Can PostgreSQL achieve zero downtime across regions?
PostgreSQL can support highly available, carefully engineered multi-region systems. Whether you reach zero or near-zero downtime depends on architecture, failover design, application behavior, and operational practice.
Does multi-region architecture solve data residency automatically?
No. Data placement must be designed and validated against applicable legal, contractual, and internal requirements, including backups and replicas.
Is multi-region database architecture always worth the complexity?
No. Weigh availability, latency, compliance, engineering effort, and cost. A well-run single-region system with a tested disaster-recovery plan can be the right answer.
Build a Multi-Region Database Architecture Around Your SaaS Requirements
Choosing between PostgreSQL and CockroachDB is a design decision with long-term operational consequences. NanoByte Technologies is a software development company that can support teams through that decision, from architecture assessment and replication strategy to database migration planning and cloud infrastructure integration.
Organizations that need enterprise multi region database architecture often look for a custom multi region database development company, or want to hire PostgreSQL database architects or distributed database engineers to extend their team. Engagements can cover SaaS database migration consulting, high-availability design, performance optimization, and zero downtime SaaS database scaling. Whether the answer is CockroachDB enterprise implementation services or a carefully engineered multi-region PostgreSQL design, the starting point is the same: your requirements, not a product preference.
Planning a multi-region SaaS architecture? Partner with NanoByte Technologies to design a database strategy around your availability, latency, data residency, and scaling requirements.
.jfif)
 (1).png)